Network Architecture
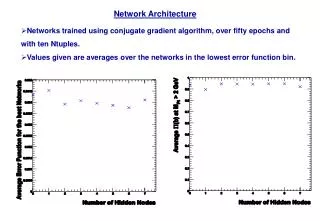
Network Architecture. Networks trained using conjugate gradient algorithm, over fifty epochs and with ten Ntuples. Values given are averages over the networks in the lowest error function bin. Training of networks. Two aspects of training studied;

Network Architecture
E N D
Presentation Transcript
Network Architecture • Networks trained using conjugate gradient algorithm, over fifty epochs and • with ten Ntuples. • Values given are averages over the networks in the lowest error function bin.
Training of networks • Two aspects of training studied; - Training sample size (number of Ntuples used) - Number of training epochs • networks with one hidden layer containing two nodes. • All networks trained using conjugate gradient algorithm.
Training input sample size • All networks trained over fifty epochs. • Results given are an average of all the networks in the lowest error function • bin.
Average purity and leakage rates as a function of sample size
Number of epochs in training • All networks trained over 10 Ntuples. Two hidden nodes
Varying the cut on Mpt • The following plots show purity and leakage rates as a function of efficiency. • The plots include the best networks for two hidden nodes and four hidden nodes • with three input variables and the best network for two hidden nodes and two input • variables.